Data annotation is the work of labeling raw data — images, text, audio, video — so an AI model can learn from it. If you've ever wondered what is data annotation, and whether you could do it for money, this guide explains it in plain English, with real examples.
Every smart AI you use was taught by people, not magic. Someone drew the boxes, tagged the words, and marked the right answers that the model copied. That someone is a data annotator, and the work is more approachable then it sounds.
I'll walk you through what data annotation means, the main types, how it differs from data labeling, where it's used, and how ordinary people get paid to do it from home.
What is data annotation?
Data annotation is the process of adding labels, tags, or markup to raw data so a machine-learning model can understand it. In plain words: you show the computer thousands of examples with the answer attached, and it learns the pattern.
A model can't "see" a photo the way you do — it sees numbers. When you draw a box around a car and type "car," you turn that image into something the model can learn from. Do that ten thousand times and the AI starts recognising cars on its own. That's the whole game: annotated examples in, a smarter model out.
The data annotation meaning is really that simple — human-added answers that teach machines. Without it, there's no self-driving car, no chatbot, and no spam filter.
A simple example of data annotation
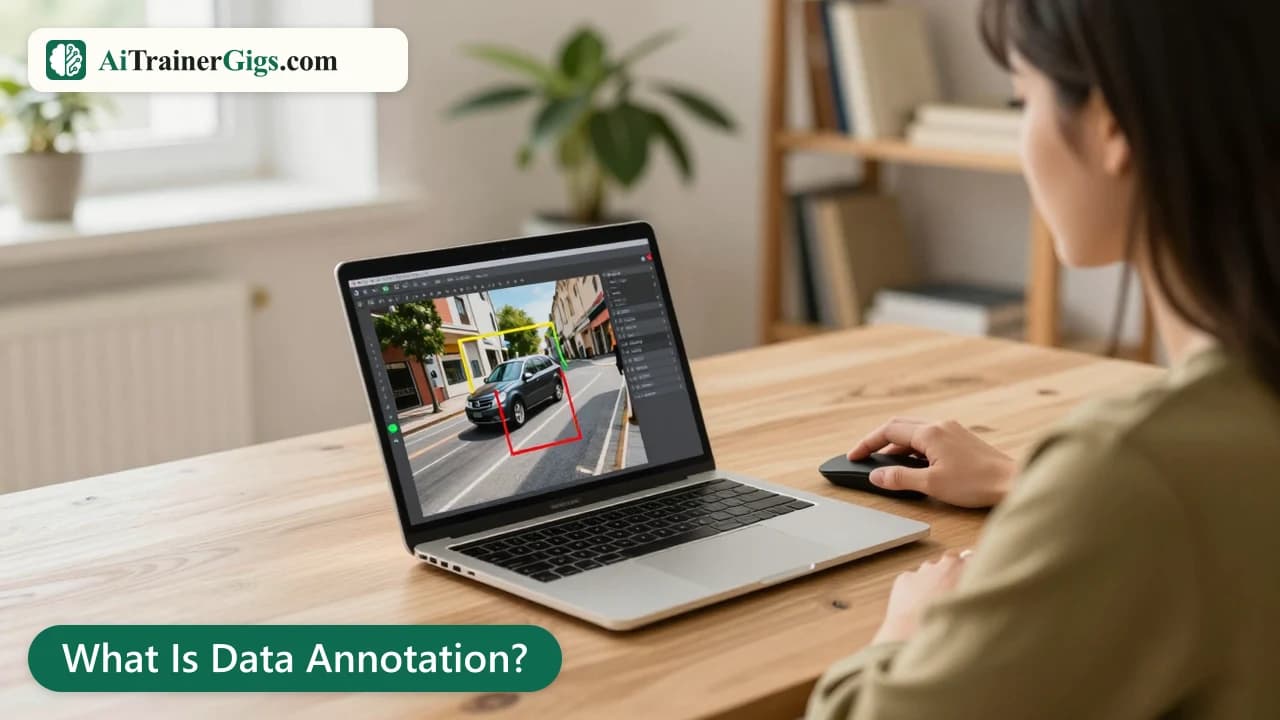
Picture a folder of street photos. Your task is to draw a rectangle around every car and label it "car," then another around each person and label it "pedestrian." That's annotation. The model later uses your boxes to learn what a car looks like from any angle, in any light.
Here's another. You're handed a pile of customer reviews and asked to tag each one "positive," "negative," or "neutral." Now an AI can read sentiment on its own. Same idea, completely different data.
Good data annotation examples are everywhere once you start noticing them — the "select all the traffic lights" check you solved this morning was you, annotating image data for free.
What one annotation task looks like
Say you open an image task. The guidelines say: "Box every vehicle. Include partly hidden ones. Do not box reflections." A photo loads. You drag a tight rectangle around the parked car, pick "car" from a dropdown, then box the van behind it even though a tree hides half of it.
A trickier one appears — is that distant shape a car or a dumpster? The rubric tells you when you're unsure, skip rather than guess. You skip it, submit the batch, and the next image loads. That's the rhythm: read the rule, apply it exactly, repeat. Simple, but the accuracy is the whole point.
The main types of data annotation
There are four big types of data annotation, grouped by the kind of data you work with.
Image and video annotation
You mark up pictures and footage — drawing bounding boxes, tracing shapes precisely (that's called segmentation), or placing dots on key points like the joints on a body. This trains the vision models behind cars, cameras, sports analysis, and retail checkout.
Text annotation
You tag words and sentences — marking names, places, and dates (entity tagging), scoring sentiment, or sorting text into categories. This is what powers search engines, chatbots, spam filters, and translation.
Audio annotation
You transcribe speech, mark who is speaking, and label sounds and accents. Voice assistants, captions, and call-centre AI all learn from annotated audio.
LLM and conversation annotation
The newest type, and a fast-growing one. You rate and rank what a chatbot replies, and sometimes write the ideal answer yourself. This is how models like ChatGPT become more helpful and safe — the industry calls it RLHF, the human feedback that teaches a model what "good" looks like.

Data annotation vs data labeling
Here's the question almost everyone asks: what's the difference between data annotation and data labeling?
Short answer: data labeling is a simple type of data annotation. Labeling usually means attaching one tag to a whole item — "this email is spam," "this photo is a cat." Annotation is the broader term that also covers richer markup — boxes, outlines, text spans, timestamps, and the relationships between objects.
Think of it this way. Marking an email "spam" is labeling. Drawing a box around every car in a street scene, transcribing an audio clip, or tagging the drug names inside a medical note is annotation.
In real life, people use the two words interchangeably, and so do most job ads. A bounding box carries a label; a label can be a simple annotation. So don't overthink the terms — if a listing says "data labeling" or "data annotation," expect very similar work.

Why good data annotation matters
There's an old saying in machine learning: garbage in, garbage out. A model is only as good as the examples it learns from. Feed it sloppy, inconsistent labels and it will make sloppy, inconsistent predictions — a mislabelled stop sign in training data can become a missed stop sign on the road.
That's why companies care so much about quality, and why careful annotators are valuable. The hard cases matter most: the blurry photo, the sarcastic review, the accented voice clip. Software can handle the easy 80%, but humans are still needed for the tricky edges where real judgement is required. That judgement is the product you're actually paid for.
What does a data annotator do?
A data annotator is the person who adds those labels. If you're wondering what is a data annotator in day-to-day terms: you log into annotation tool, open a queue of tasks, and label items one after another against a set of guidelines (the "rubric").
Most of the work is remote, done from a laptop, and paid per task or per hour. You don't need to code. You do need patience, attention to detail, and the ability to follow instructions exactly — one careless batch can drop your quality score and quietly cut off the better projects.
For the honest, hour-by-hour version of the role, I wrote up what the day-to-day work is actually like in a separate post.
Where data annotation powers AI
Annotation sits behind almost every AI product you touch:
- Self-driving cars learn roads, signs, and pedestrians from millions of annotated frames.
- Chatbots and LLMs get safer, clearer answers from rated and ranked responses.
- Medical imaging AI learns to flag tumours because specialists annotated the scans.
- Voice assistants understand you because someone transcribed and labelled speech.

Every one of these started with a human marking up examples. The better the annotation, the better the AI — which is exactly why companies pay real money for careful annotators.
Can you get paid to do data annotation?
Yes — and you dont need a degree or prior experience to start. Companies hire remote annotators through platforms that match tasks to your skills. Pay is usually $10–$25 an hour for general work, and more for specialised projects like coding, medical, or multilingual data.
A few honest things to expect before you dive in:
- Work can be inconsistent — some weeks are busy, others are quiet.
- You'll usually pass a short assessment before paid tasks appear.
- Your quality score decides how much work you unlock, so go slow and accurate at the start.
What helps most is simple: clear writing, careful reading of the guidelines, and real expertise in a subject (a second language, a medical or legal background, coding).
You can get started in four steps:
- Pick a platform that matches your strength — general tasks, coding, or a language you speak.
- Pass the assessment. Treat it like an interview: read every instruction twice and don't rush.
- Go slow on your first tasks. Your early accuracy sets the quality score that unlocks better-paid work.
- Add a second platform once the first is steady, so a quiet week doesn't zero your income.
If that sounds like you, browse current data annotation jobs, or the closely related remote data labeling work, to see what's open and what it pays.
Conclusion
So, what is data annotation? It's the human work of labeling data — drawing boxes, tagging words, rating answers — that teaches AI how the world works. It's the quiet foundation under every model, and it's one of the most accessible ways to earn from the AI boom without writing a single line of code.
Start small, follow the guidelines closely, and treat your quality score like gold. Do that, and you'll come to understand AI from the inside — and get paid while you learn.